

In this video· click a step to jump to it
Test recording
Relay — multi-model answer walkthrough
123,523 ms · 429,486 pixels changed
We built this regression test for relayknowledge.com — it's yours to keep, free.
Take this test with you
This is a real Playwright test, recorded against relayknowledge.com. Claim it into your own workspace and re-run it on every deploy — free.
export async function test(page, baseUrl, screenshotPath, stepLogger) {
  const SITE = (baseUrl || 'https://relayknowledge.com').replace(/\/$/, '');
  let n = 0;
  const shot = async (slug) => {
    n += 1;
    const p = String(screenshotPath).replace(/\.png$/i, '') + '-' + String(n).padStart(2, '0') + '-' + slug + '.png';
    await page.screenshot({ path: p, fullPage: false });
    stepLogger.log('frame ' + n + ' ' + slug + ' :: ' + page.url());
  };
  const settle = async (ms) => { await page.waitForTimeout(ms); };
  const go = async (path, ms) => {
const r = await page.goto(SITE + path, { waitUntil: 'domcontentloaded' });Checks run
Notes from the demo run
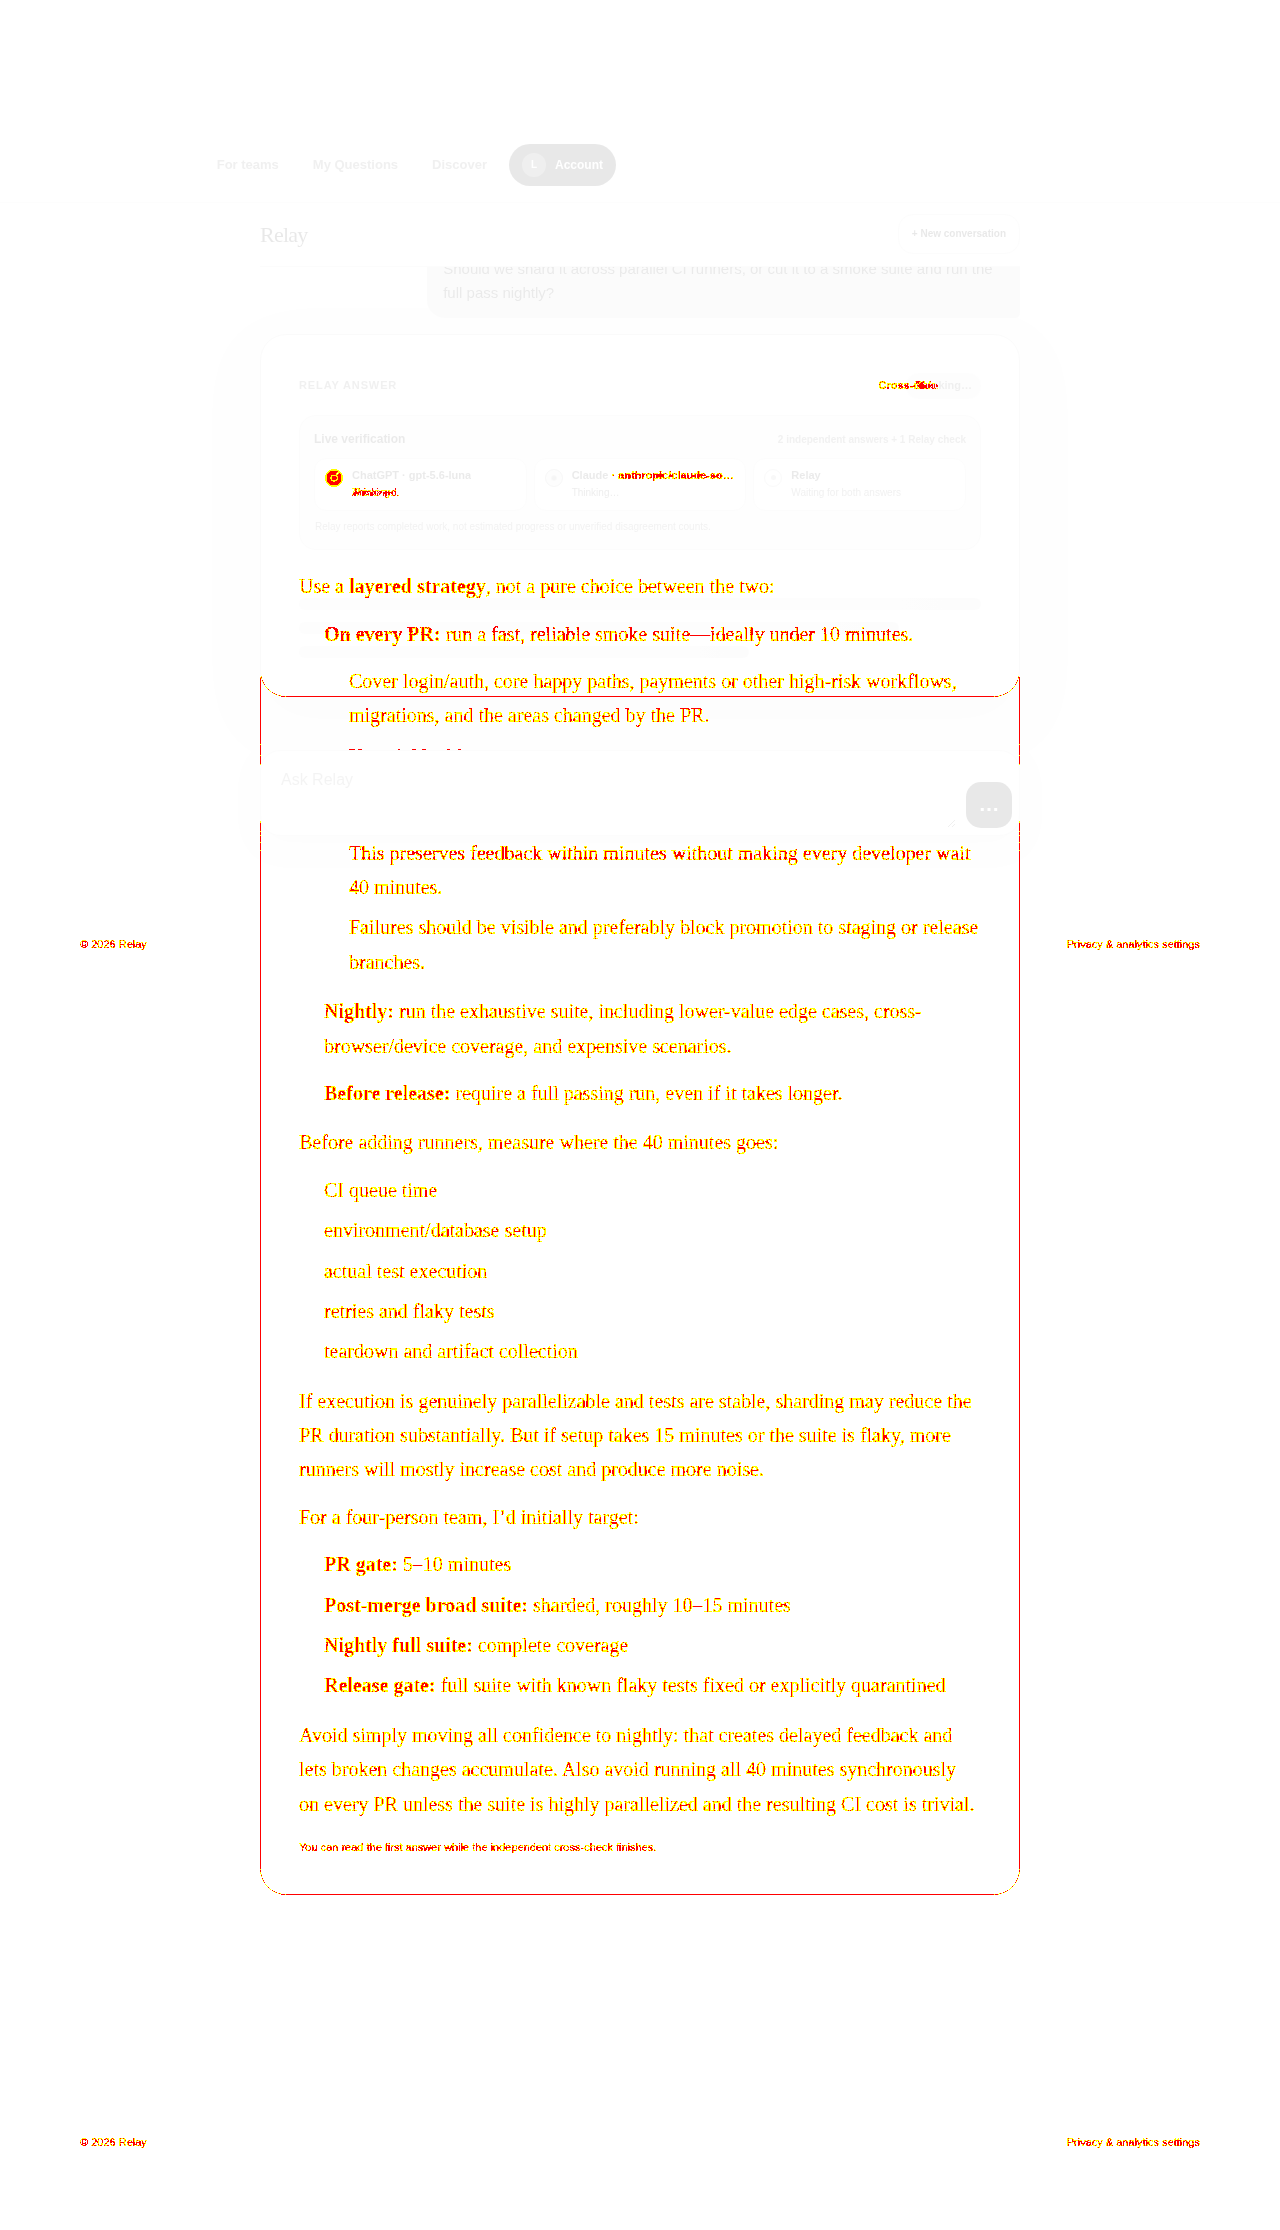
AI-generatedWe signed in to relayknowledge.com with Google, picked the Compare-two-options mode, and asked Relay a real engineering question: shard a 40-minute end-to-end suite across CI runners, or cut it to a nightly smoke pass. Two models answered independently, Relay adjudicated, and the whole thing finished inside 30 seconds. The adjudication layer is the product and it holds up - the blind-spot panel caught something neither model said.
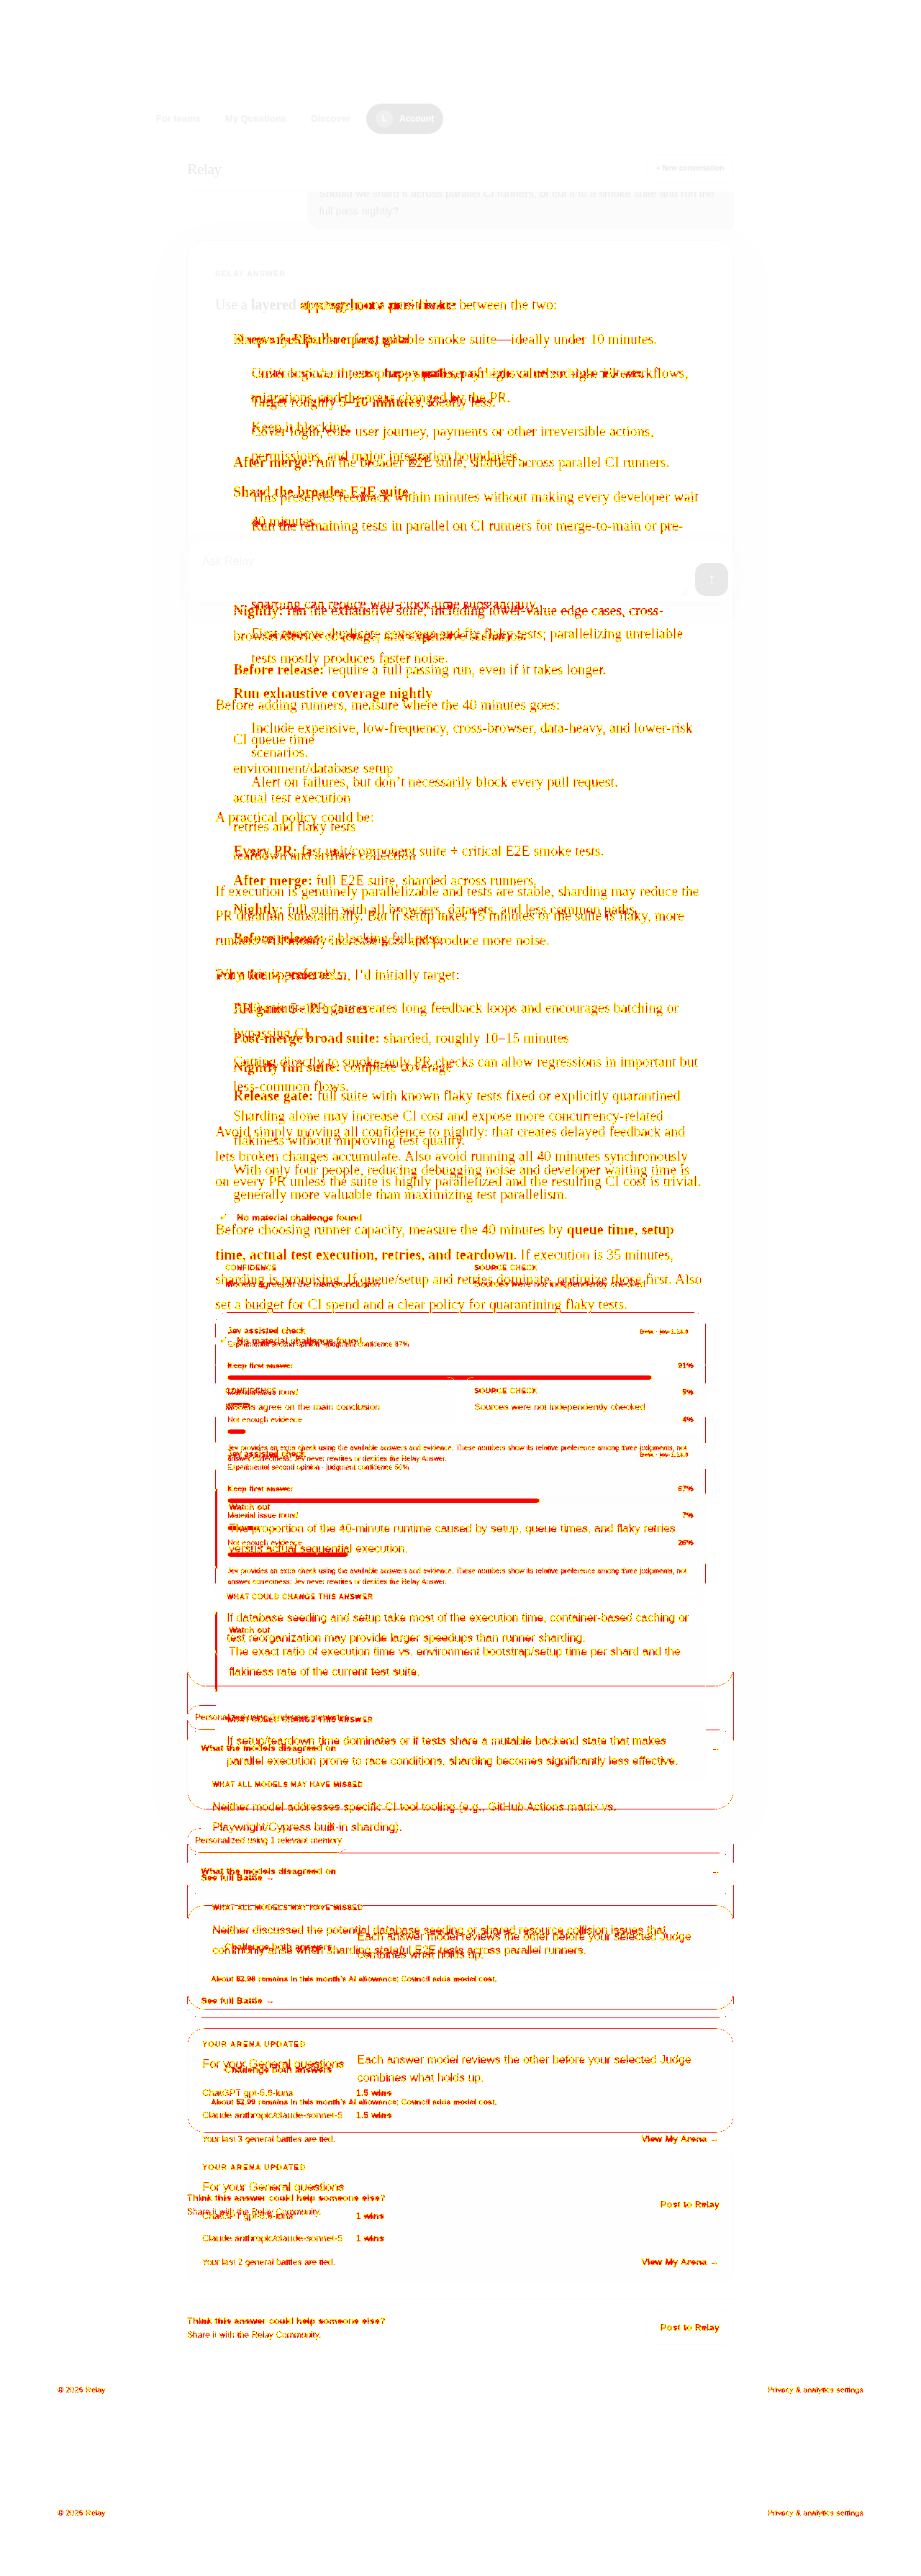
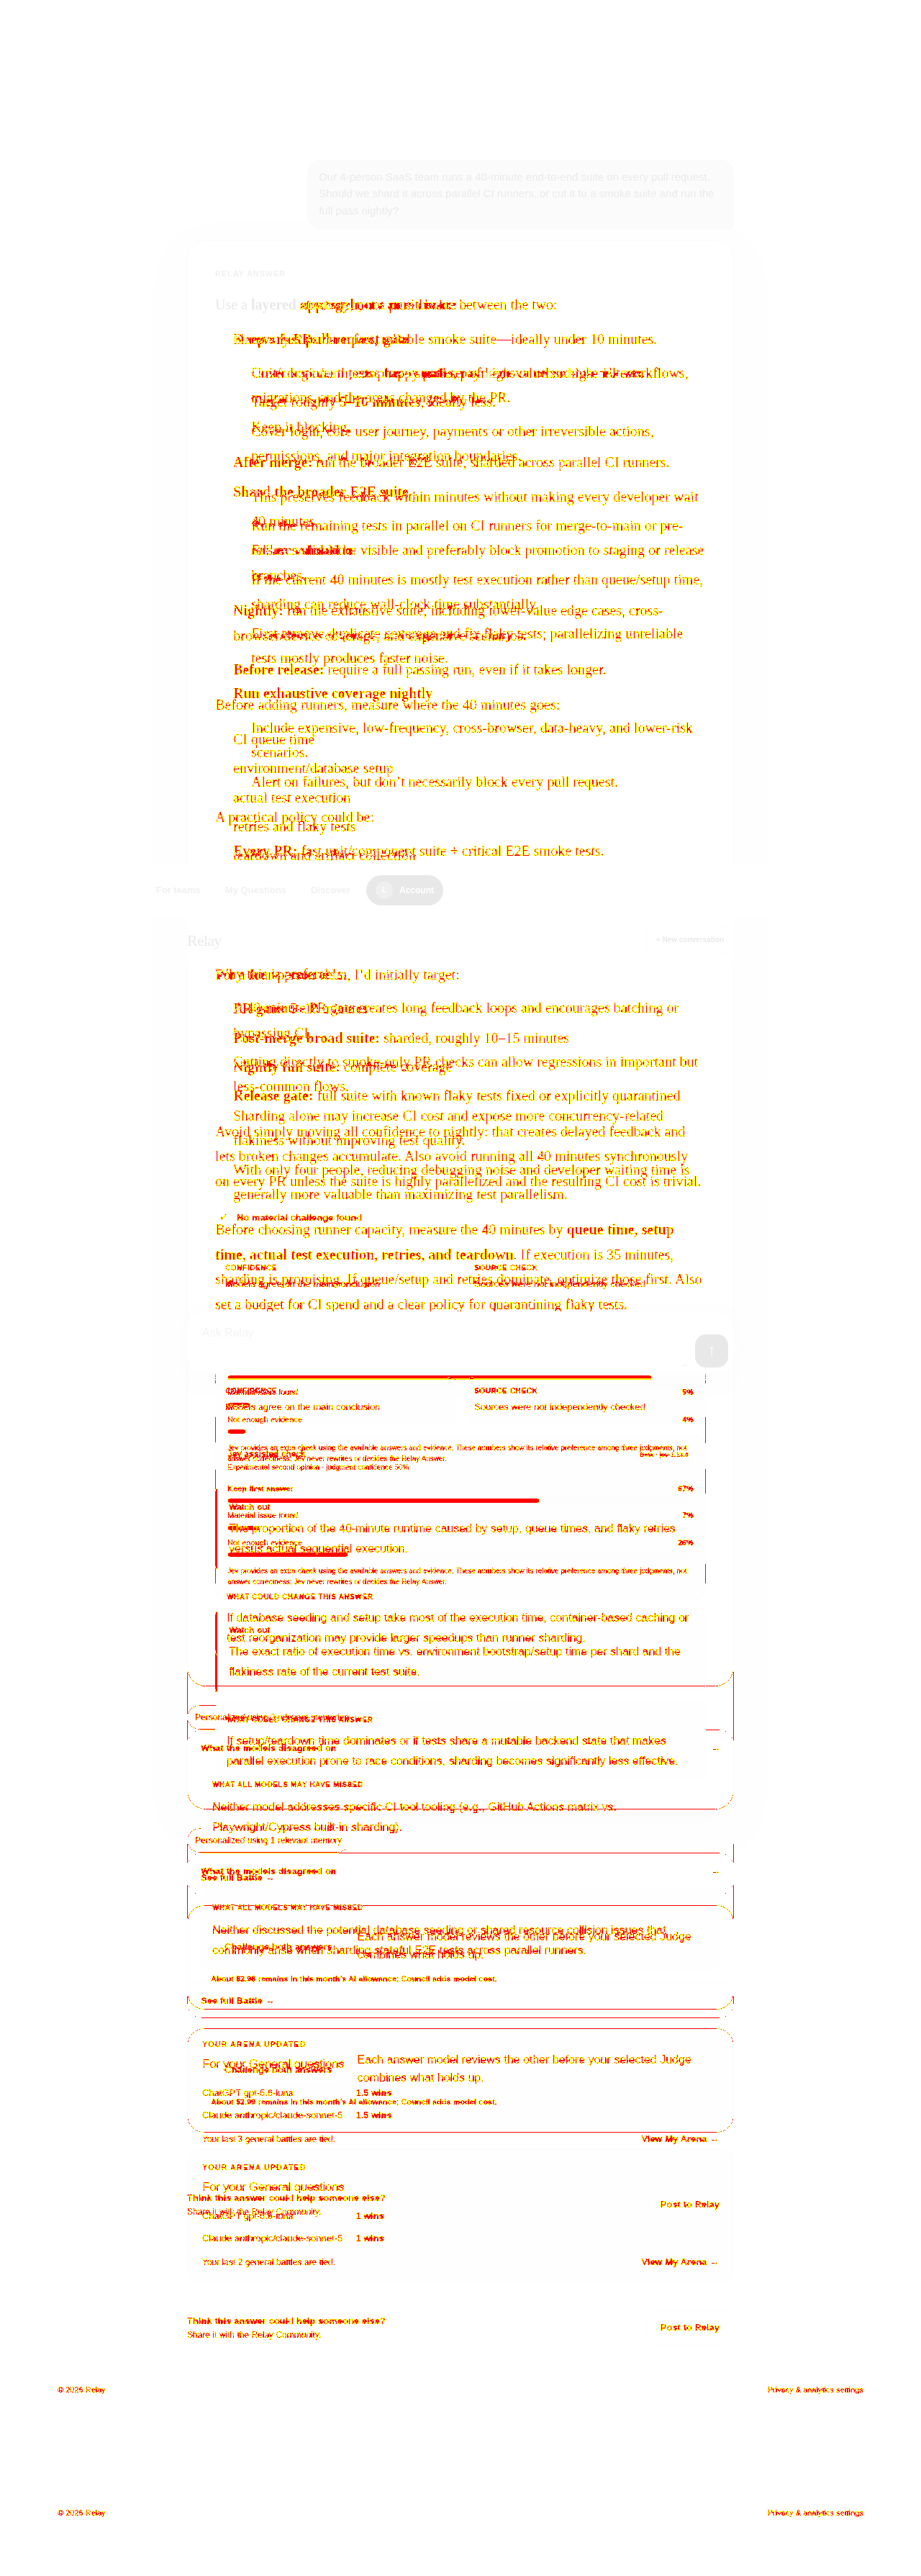
- 'What all models may have missed' earns its placeOn our question it returned: neither model addressed specific CI tooling such as GitHub Actions matrix versus Playwright/Cypress built-in sharding. That is a genuine gap, not a hedge, and it is the single clearest argument for running two models instead of one.
- The confidence panel separates agreement from verification'Models agree on the main conclusion' sits next to 'Sources were not independently checked'. Most AI products collapse those two into one confidence number; keeping them apart is the honest call.
- The Jev assisted check shows its workingKeep first answer 91% / Material issue found 5% / Not enough evidence 4%, with a note that Jev never rewrites or decides the Relay Answer. A reader can tell exactly how much weight the second opinion carried.
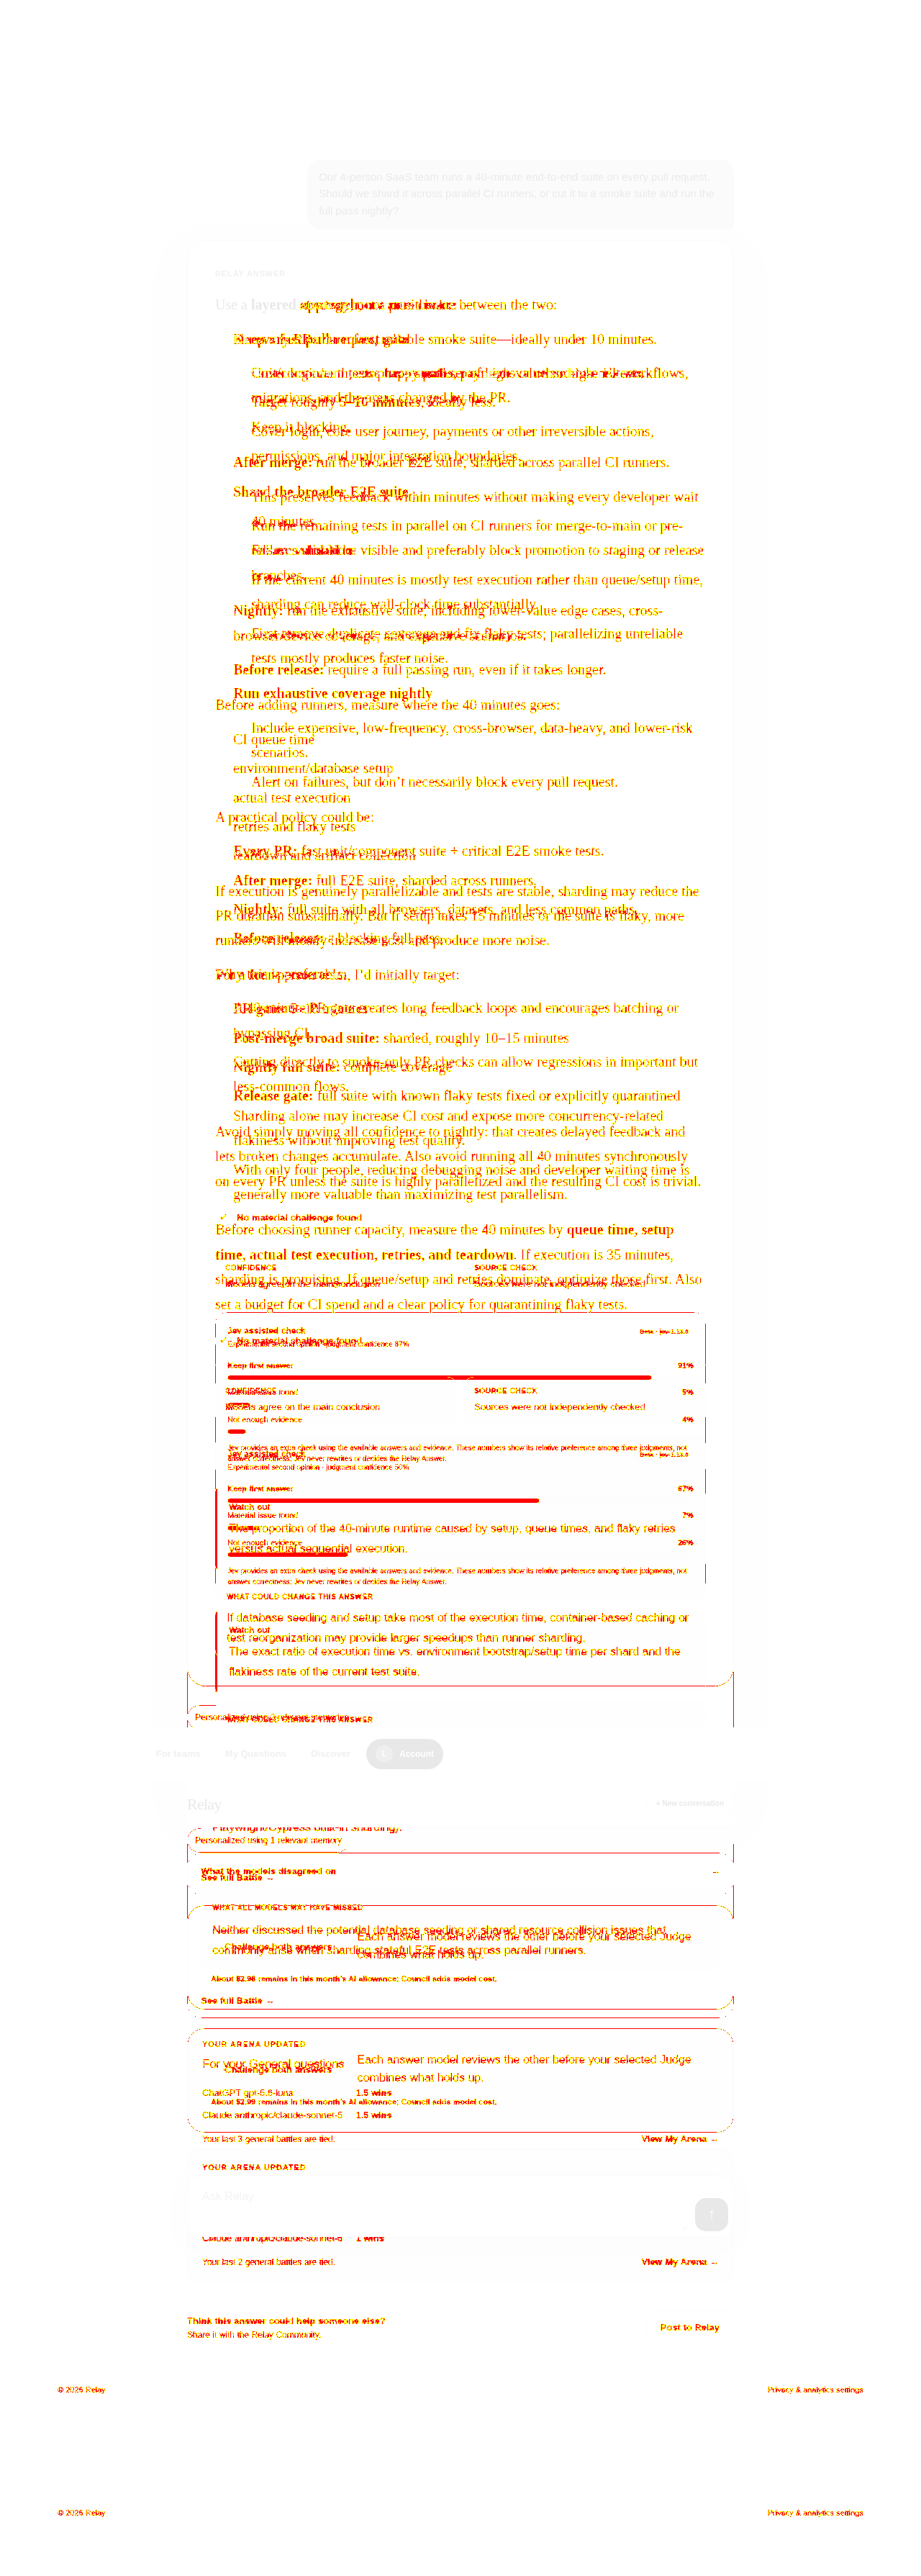
- The arena turns every question into a running scoreboardAfter three questions it showed ChatGPT 1.5 wins and Claude 1.5 wins for our General category. Personal, accumulating, and a real reason to come back.
- A conversation URL cannot be opened, shared or refreshedAfter an answer completes the address bar shows /conversation/<id>, but pasting that URL into a new tab renders the marketing homepage - the conversation only exists in client state. Any reader who bookmarks, refreshes or shares that link loses the answer. Serving the conversation server-side for its own id would fix it.
- The Ask button does not respond to a scripted clickActivating the submit button programmatically fires only your analytics call; the question is never sent, and the composer just sits there with no error. Only a real pointer press reached /api/ask. Anything driving the page that is not a hand on a mouse - our run, and plausibly some assistive tech - silently fails to ask a question.
- Challenge both answers / Council·Not exercised - it adds model cost to the account's allowance.
- Post to Relay·Not exercised - we do not publish to a founder's community feed from a demo account.
5 visual changes










Share this run
Proof your app is not AI slop
This test was built for relayknowledge.com — claim it free
One click copies the test and baseline screenshots into your own Lastest workspace. Re-run on every deploy and catch regressions before your users do — free, no card required.